Assets & Files
Assets are pointers to data resources that are registered with Ellf and can refer to files, directories and machine learning models on your cluster, as well as any other sources like data from an API call or a custom remote database. In addition to assets, you can upload and manage Python packages on your cluster and create datasets used to store data and annotations. In the web application, the ClusterAssets page shows you an overview of assets available on your cluster.
Assets
Any loadable files and resources
Datasets
Annotated data created by tasks
Packages
Python packages of recipes and code
Recipes
Tasks, actions, agents and services
Use Ellf to manage files and resources
If you’ve connected Ellf to your coding assistant, it will be able to upload files and create and manage assets for you. It can also help you pick the right kinds and format your files accordingly.
Asset types
Assets cover all common data types like input files and resources, raw datasets, models and vectors, match patterns, label schemes and annotation guidelines. You can also implement your own custom types for different files and formats. When uploading assets to the cluster, you can specify their kind, i.e. the type of asset. Ellf includes the following built-in kinds that also come with their own dataclasses:
| Input data | input | Any input data resources |
| Models | model | Loadable spaCy models |
hf_model | Loadable Hugging Face models | |
vectors | Loadable embeddings and word vectors | |
| Configs | config | spaCy model and training configs |
| Results | results | Training and experiment results |
| Patterns | patterns | Match pattern files for spaCy and Prodigy |
| PDFs | pdf | Collection of PDF documents |
layout | Extracted PDF layouts | |
tessdata | OCR data for Tesseract | |
| Label schemes | labels | Label schemes and definitions for tasks and agents |
| Instructions | instructions | Annotation guidelines for annotators and agents |
Assets that are always Markdown or JSON files under the hood, like label schemes, instructions and results, can also be previewed in the web app, indicated by the icon.
Data and data files
Naturally, data is one of the most important parts of many workflows and you often want to start by adding your input data to the app. The hybrid cloud architecture of Ellf means that all of your data stays private and on the data processing cluster hosted by you, and our servers only store a record of the data, called an “asset”.
Assets can point to pretty much anything that’s loadable – commonly, this includes files and directories of files, but it can also include remote resources from a database or an API. See the section on custom assets for details on how to implement your own dataclasses for custom asset types and associated logic like loading. Ellf also ships a built-in PDF asset type for annotating scanned and digital documents.
Models
Models are a sub-type of assets, since they’re also just collections of files under the hood. They can be required in recipes, produced by actions (e.g. after training), or used by agents to perform specific tasks.
Models can be uploaded to your cluster using publish data, pointing the destination path to a location on your cluster’s storage bucket. You can also produce models from action recipes – for instance, training a model from a dataset will automatically register the resulting model as a new asset. To use a model in a recipe, annotate the argument with the Model type, which provides a load method that returns the loaded model. For more details and examples, see the recipe development guide.
Hugging Face checkpoints are stored as their own asset kind, hf_model, because they can’t be loaded as spaCy pipelines. They’re created by downloading a model from the Hub or fine-tuning one on your annotations, and used by the Hugging Face model agent and model push. They never appear where a spaCy Model is expected. In your own recipes, use the HfModel type.
Training a model with the built-in recipes will automatically create a results asset that stores the experiment results as JSON.
PDF documents
PDFs are a built-in asset type (kind="pdf") for annotating documents – drawing regions on pages, correcting OCR, or labeling text spans over the extracted layout. Unlike a plain input asset, a PDF asset is a folder holding the source PDFs alongside their rendered page images and a manifest, so its pages are rendered once and reused by every annotation task built from it. See Working with PDFs for the recipes and end-to-end workflow.
Contracts
- Kind
- Size
- 312 MB
- Uploaded
- Mar 4, 2026, 14:22
- Updated
- Mar 4, 2026, 14:31
- Path
- /mnt/nfs/data/contracts
- Documents
- 128
- Pages
- —
- Images
- not rendered
Not in use
Not used by anything yet.
Contracts
- Kind
- Size
- 312 MB
- Uploaded
- Mar 4, 2026, 14:22
- Updated
- Mar 9, 2026, 09:05
- Path
- /mnt/nfs/data/contracts
- Documents
- 128
- Pages
- 1043
- Images
- rendered
Used by 1
- taskAnnotate contract clauses
Keep the asset available
Annotations reference the page images by URL rather than embedding them. The asset needs to stay on the cluster so those URLs stay resolvable – deleting it (or its rendered pages) breaks the page images in any dataset built from it.
Label schemes
Label schemes are a built-in asset type (kind="labels") for the labels of a task and their definitions, stored as a JSON file. The scheme lists the labels in order, and each label can have a description, a list of concepts to exclude, and examples of the right answer. Annotators see a label’s description when they hover it in the annotation app, and agents assigned to the task include the definitions in their prompts. Because a scheme is an asset, you can write it once and reuse it across tasks and agents.
{
  "PARTY": {
    "description": "A person or organization that is a party to the contract.",
    "do_not_mark": [
      "third parties that are only mentioned, like a bank or regulator",
      "generic references like \"the parties\" or \"each party\""
    ],
    "examples": [
      {
        "text": "This Agreement is made between Acme Corp. and Jane Smith.",
        "spans": [
          { "text": "Acme Corp.", "label": "PARTY" },
          { "text": "Jane Smith", "label": "PARTY" }
        ]
      },
      {
        "text": "Payments are processed by First National Bank.",
        "spans": []
      }
    ]
  },
  "EFFECTIVE_DATE": {
    "description": "The date the contract takes effect.",
    "do_not_mark": ["the date the contract was signed, if it's different", "end or renewal dates"],
    "examples": [
      {
        "text": "This Agreement shall be effective as of March 1, 2025.",
        "spans": [{ "text": "March 1, 2025", "label": "EFFECTIVE_DATE" }]
      }
    ]
  },
  "GOVERNING_LAW": {
    "description": "The jurisdiction whose laws govern the contract."
  },
  "AMOUNT": {}
}{
"NDA": {
"description": "A non-disclosure agreement, whose main purpose is to keep shared information confidential.",
"do_not_mark": ["other contracts that only include a confidentiality clause"],
"examples": [
{
"text": "The Receiving Party shall hold all Confidential Information in strict confidence and use it solely to evaluate the Proposed Transaction.",
"label": "NDA"
}
]
},
"EMPLOYMENT": {
"description": "An agreement between an employer and an employee about a job, its pay and its duties.",
"do_not_mark": ["agreements with independent contractors or consultants"],
"examples": [
{
"text": "The Company agrees to employ the Employee as Senior Engineer at an annual salary of $120,000.",
"label": "EMPLOYMENT"
},
{
"text": "The Consultant is an independent contractor and not an employee of the Client."
}
]
},
"LEASE": {
"description": "An agreement to rent property or equipment for a period of time."
},
"LOAN": {}
}The file maps each label to an object, and the order of the keys is the order of the labels. All keys of a label are optional, and a label without a definition is {}. Under the hood, the file can be converted to a LabelScheme object.
description | What the label covers, in a sentence or two, as you’d explain it to a new annotator. |
do_not_mark | Concepts that should not get the label. This is often the most useful part of a definition, since it covers the cases annotators and models disagree on. |
examples | Texts with the right answer. Each example has a "text".Span annotation: Examples can include a list of "spans" with a "text", "label" and to distinguish multiple occurrences, an optional "start" and "end" character offsets like in Prodigy’s format. An empty list means nothing to mark.Text classification: Examples include the "label" that applies to the text, or no "label" key if it doesn’t apply. |
The built-in task recipes for named entities, spans and text classification take either a list of labels or a label scheme. You can switch between a list or an asset in the form, or use the --label-scheme argument instead of --label on the CLI. The built-in agent recipes use the task’s label definitions by default and can add their own scheme on top. In custom recipes, use the Labels type and the AgentLabels dataclass.
Use Ellf to develop label schemes
If you’ve connected Ellf to your coding assistant, the data annotation module can help you design and create label schemes for your task. If you have already annotated data, you can also point it to the dataset to automatically create and upload label definitions, based on your annotations.
Annotation instructions
Annotation instructions are a built-in asset type (kind="instructions") for Markdown documents that can be viewed by annotators during annotation. They’re shown in the Prodigy app by clicking the icon in the sidebar or pressing the H key. If instructions are available for a task, they can also be used by agents assigned to it.
In the built-in task recipes, instructions can usually be added in the Annotation settings section at the bottom of the forms and via the --settings.instructions argument on the CLI. In custom recipes, the annotation settings section can be added using the AnnotationSettings dataclass as an argument.
Agents can also have their own instructions, which are combined with the instructions of the task they’re assigned to (unless explicitly ignored). The built-in agent recipes have a settings section and a --settings.instructions argument, and in custom agent recipes you can add it using the AgentSettings dataclass.
Use Ellf to create annotation guidelines
If you’ve connected Ellf to your coding assistant, the data annotation module can help you design label schemes, identify edge cases and develop comprehensive annotation instructions for your annotators and agents. You can also ask Ellf to create guidelines based on existing annotated datasets or label definitions.
Datasets
Datasets are named collections of data and annotations in Prodigy’s JSON format, stored in the database on your cluster. When you start an annotation task, you typically provide the name of a new or existing dataset to save the collected annotations to. Datasets can then be used for training and evaluating models and performing other analysis. The datasets command lets you manage your datasets.
Exporting datasets
The datasets export command downloads examples from an existing dataset to a file, e.g. to inspect it locally or to integrate the data into a larger automation pipeline. Datasets are stored in Prodigy’s JSONL (newline-delimited JSON) format. Also see the docs on Prodigy’s annotation interfaces for more details on the data format and structure they produce.
{"text":"Uber\u2019s Lesson: Silicon Valley\u2019s Start-Up Machine Needs Fixing","meta":{"source":"The New York Times"},"_input_hash":1886699658,"_task_hash":-1952856502,"tokens":[{"text":"Uber","start":0,"end":4,"id":0},{"text":"\u2019s","start":4,"end":6,"id":1},{"text":"Lesson","start":7,"end":13,"id":2},{"text":":","start":13,"end":14,"id":3},{"text":"Silicon","start":15,"end":22,"id":4},{"text":"Valley","start":23,"end":29,"id":5},{"text":"\u2019s","start":29,"end":31,"id":6},{"text":"Start","start":32,"end":37,"id":7},{"text":"-","start":37,"end":38,"id":8},{"text":"Up","start":38,"end":40,"id":9},{"text":"Machine","start":41,"end":48,"id":10},{"text":"Needs","start":49,"end":54,"id":11},{"text":"Fixing","start":55,"end":61,"id":12}],"_session_id":null,"_view_id":"ner_manual","spans":[{"start":0,"end":4,"token_start":0,"token_end":0,"label":"ORG"},{"start":15,"end":29,"token_start":4,"token_end":5,"label":"LOCATION"}],"answer":"accept"}
{"text":"Pearl Automation, Founded by Apple Veterans, Shuts Down","meta":{"source":"The New York Times"},"_input_hash":1487477437,"_task_hash":-1298236362,"tokens":[{"text":"Pearl","start":0,"end":5,"id":0},{"text":"Automation","start":6,"end":16,"id":1},{"text":",","start":16,"end":17,"id":2},{"text":"Founded","start":18,"end":25,"id":3},{"text":"by","start":26,"end":28,"id":4},{"text":"Apple","start":29,"end":34,"id":5},{"text":"Veterans","start":35,"end":43,"id":6},{"text":",","start":43,"end":44,"id":7},{"text":"Shuts","start":45,"end":50,"id":8},{"text":"Down","start":51,"end":55,"id":9}],"_session_id":null,"_view_id":"ner_manual","spans":[{"start":0,"end":16,"token_start":0,"token_end":1,"label":"ORG"},{"start":29,"end":34,"token_start":5,"token_end":5,"label":"ORG"}],"answer":"accept"}
{"text":"How Silicon Valley Pushed Coding Into American Classrooms","meta":{"source":"The New York Times"},"_input_hash":1842734674,"_task_hash":636683182,"tokens":[{"text":"How","start":0,"end":3,"id":0},{"text":"Silicon","start":4,"end":11,"id":1},{"text":"Valley","start":12,"end":18,"id":2},{"text":"Pushed","start":19,"end":25,"id":3},{"text":"Coding","start":26,"end":32,"id":4},{"text":"Into","start":33,"end":37,"id":5},{"text":"American","start":38,"end":46,"id":6},{"text":"Classrooms","start":47,"end":57,"id":7}],"_session_id":null,"_view_id":"ner_manual","spans":[{"start":4,"end":18,"token_start":1,"token_end":2,"label":"LOCATION"}],"answer":"accept"}
{"text":"Women in Tech Speak Frankly on Culture of Harassment","meta":{"source":"The New York Times"},"_input_hash":-487516519,"_task_hash":62119900,"tokens":[{"text":"Women","start":0,"end":5,"id":0},{"text":"in","start":6,"end":8,"id":1},{"text":"Tech","start":9,"end":13,"id":2},{"text":"Speak","start":14,"end":19,"id":3},{"text":"Frankly","start":20,"end":27,"id":4},{"text":"on","start":28,"end":30,"id":5},{"text":"Culture","start":31,"end":38,"id":6},{"text":"of","start":39,"end":41,"id":7},{"text":"Harassment","start":42,"end":52,"id":8}],"_session_id":null,"_view_id":"ner_manual","answer":"accept"}
Keep in mind that the data may contain references to files hosted on your cluster, like image or audio file paths. If you want to export all assets and datasets, e.g. for backup purposes, you can use the ellf export command.
Packages and recipes
Recipe functions for tasks, actions, agents and services are shipped as Python packages and Ellf manages those centrally alongside assets, to ensure each worker of the cluster has the correct set of package dependencies available when executing a recipe. Collections of recipes are uploaded as versioned Python packages and you’ll be able to see the recipe version used by a task, action agent or service in the app and CLI info.
Packages can contain multiple recipes and your cluster can have multiple versions of the same package. For the built-in recipe packages, Ellf will automatically keep your cluster up to date and install new versions when they’re available. Jobs that use an older version of a recipe will still work as expected and you’ll see a notification in the app that a new package version is available.
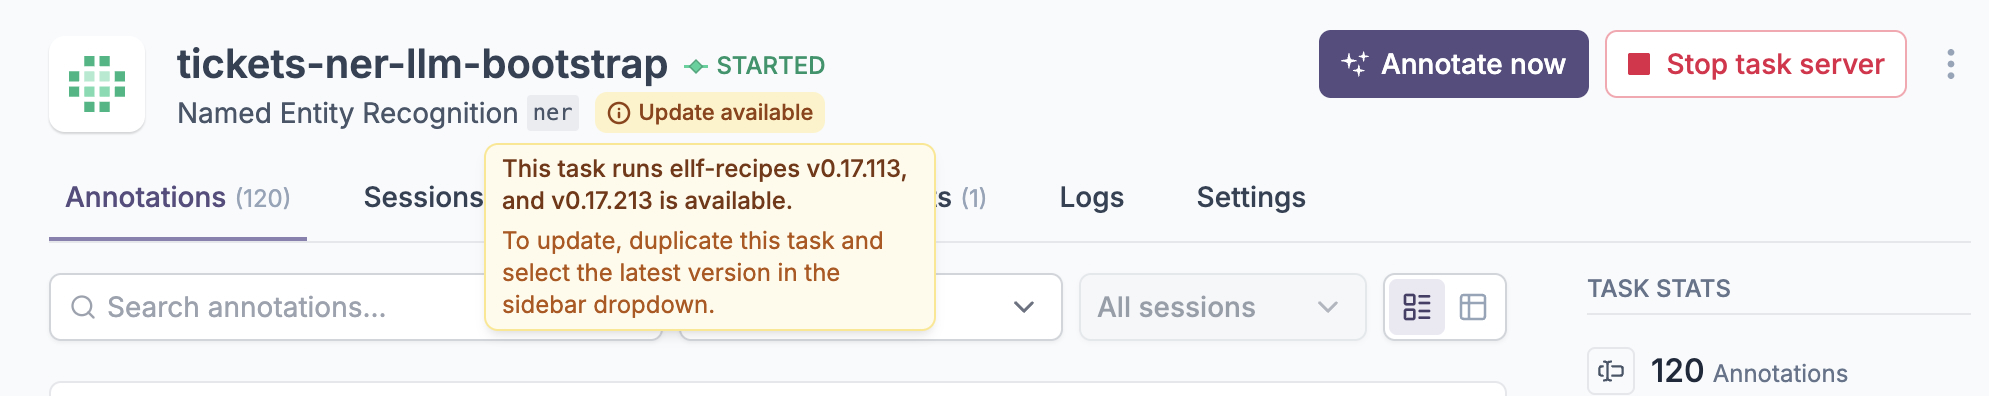
To update a job to use the latest version, you can duplicate it and select the new version in the package dropdown in the sidebar. On the CLI, you can copy the job command from the job info or Settings tab in the app and re-run it with a new name, or ask your coding assistant to do it for you.
When developing your own custom recipes, you can group them together in packages that share logic and dependencies. If a recipe package requires external dependencies, those will be installed on the cluster whenever Ellf spins up a new job. To upload a new version of your recipes, increment the Python package version and re-publish it with publish code.
Documentation
Publishing data assets
The easiest way to upload and publish data to your cluster is by using the publish data command. This takes care of uploading the files to the storage bucket on your cluster and creates a record of the asset in Ellf so you can use it within the app. The {__data__} variable in the destination path is a path alias built in by default, which refers to the data directory on your cluster’s shared storage – a cloud storage bucket or a shared disk, depending on how your cluster is configured.
For a quick and simple upload via your browser, you can also select AssetsUpload asset in the app. If your data is already on the Hugging Face Hub, the built-in hf_dataset_import action brings a dataset in as an input asset directly, without downloading it to your machine first.
$ellfpublish
data
./example.jsonl
"{__data__}/example/data.jsonl"
--name "My first asset"--version 1.0.0--kind input--loader jsonl
Why the loader matters
The loader says how Prodigy should read the asset, and it’s also what decides whether a recipe’s form offers it in the asset picker, so it is recommended to set --loader whenever you publish. See Input for how a recipe narrows down the assets it accepts.
Publishing PDFs
PDF assets publish a little differently. You don’t pass a dest – they’re rooted automatically – and registering the source files is only the first step: the pages need to be rendered before the asset can be annotated. Add --render to do both at once, e.g. ellf publish data ./contracts/ --name contracts --kind pdf --render. See the publish data reference for the full arguments.
The newly created asset will now show up in ClusterAssets in the UI and in assets list on the CLI. The copied files are also shown when you run files ls on the assets directory.
Assets can also be created dynamically from Python within recipes, for example to save preprocessed data or import from an internal or external resource like a database. If your data source requires authentication, you can use the built-in secrets feature to securely make your API keys or credentials available to the recipe.
Working with PDFs
Ellf ships a set of recipes for annotating PDF documents. They all build on the built-in PDF asset type, so the first step is always to publish and render your documents as a pdf asset. Rendering rasterizes each page once, via the --render flag of publish data or as the pdf_ingest action. From there, the recipes reuse those page images so you never re-render. There are two main workflows, depending on what you want to annotate.
Region annotation and OCR correction
This workflow treats each page as an image and is ideal for scanned documents, forms, or extracting text from specific regions:
- PDF Image Annotation (
pdf_image) – draw labeled bounding boxes and regions directly on the rendered pages. By default all the pages of a document are grouped into a single task that you page through together, keeping them in context. Setsplit_pagesto instead put each page in the queue as its own separate task, which is handy for distributing a long document across annotators. - PDF OCR Correction (
pdf_ocr_correct) – takes the boxes annotated in the previous step, crops each region from the page, runs Tesseract OCR over it, and presents the extracted text for you to correct. Filter which boxes to OCR by label, and OCR in other languages with your own Tesseract language data.
Custom OCR language data
Only English (eng) is bundled in the cluster image, so to OCR in any other language you need to upload its Tesseract data files as an asset of kind tessdata. Take the .traineddata file(s) you need (for example from the tessdata repository) and publish them with --kind tessdata, either as a single file or as a directory holding several. Uploading in the app picks the kind for you from the .traineddata extension. Each file name must match the language code you pass (e.g. pol.traineddata for pol, combined as eng+pol). Only tessdata assets are offered in the Tesseract language data field, so your data files don’t show up wherever annotation data is expected, and vice versa.
Layout-based span annotation
This workflow extracts the document’s text and layout so you can annotate spans (e.g. for NER) over real tokens, with the page image shown alongside for context. It’s a two-recipe process:
- Extract PDF layout (
pdf_layout_fetch) – an action that runsspacy-layoutover the PDFs to extract text, tokens and layout structure (headings, lists, paragraphs) into a separate, lightweight layout asset. Prepare it infocusmode to annotate only specific layout types (e.g.textorlist_item) section-by-section, or leave it full-page. - PDF Span Annotation (
pdf_spans) – annotate text spans over the extracted layout, with the rendered page shown alongside for reference. It reuses the layout asset’s source PDF automatically, so you only select the layout asset. Pick an annotation mode: view whole pages grouped into one task, one task per page, or – for a layout asset prepared with focus – section-by-section. You label whatever spans your scheme defines, not only named entities, and can optionally select a spaCy model with an NER component to pre-highlight its entity predictions as suggestions.
Pick the workflow that matches your data
Reach for region annotation + OCR when the text isn’t reliably extractable (scans, images, complex forms) and you need to define and read regions yourself. Reach for layout-based spans when the PDFs have a recoverable text layer and you want to label spans over the real text, the way you would with NER or span categorization on plain text.
Path aliases
Assets are pointers to files that can be located anywhere, most commonly on your cluster. Under the hood, those files will be added to a cloud storage bucket, e.g. an S3 bucket if you’re using AWS. To make it easier to manage file paths on your cluster, Ellf lets you create named path aliases using the paths command. When managing files and creating assets, you can then use the alias as a variable in the path, e.g. {alias}/ so you don’t have to repeat the full URL. Built-in path aliases are formatted between __ and can also be used in custom path aliases.
| Built-in alias | Description |
|---|---|
__nfs__ | The path to the NFS drive. |
__data__ | The data directory on the cluster’s shared storage. |
For example, you can have an alias {train} that points to {__data__}/training. After adding a path, you can then use it in commands like publish and files.
Secrets
Secrets let you securely manage API keys and other credentials across your organization, which you can then select and use in recipes – for example, if you need to connect to a model via an API. Under the hood, secrets are named pointers and you can view and manage them using the secrets command or via ClusterAssetsSecrets in the UI. Secret values are stored only on your cluster and never sent to our servers.
Adding secrets
You can create a secret using secrets create on the CLI or via the UI. If you don’t provide a --value, you’ll be prompted to enter it interactively so it doesn’t appear in your shell history.
Hiding the secret in your shell history
To make sure your secret isn’t saved in the history, don’t set the --value and enter it when prompted instead. You can also prefix the command with a space to keep it out of history if your shell is configured with HISTCONTROL=ignorespace in bash or setopt HIST_IGNORE_SPACE in zsh.
Using secrets in recipes
Recipes for tasks, actions, agents and services can require secrets as their arguments, e.g. to authenticate with an API. In the UI, you can then see a dropdown of the available secrets. On the CLI, you can simply provide the secret name.
$ellfagents
create
gemini_agent"Gemini Auto-Labeler Agent"--model gemini-2.0-flash
--api-key GEMINI_API_KEYThe built-in Hugging Face recipes take an hf_token secret holding your own access token from huggingface.co. It’s optional for recipes that only read public repos, and required for pushing to the Hub and for the Hugging Face LLM agent.
If you’re developing your own recipes, you can require the Secret type for an argument, which will then allow the user to select a secret and pass an instance of it to your recipe function. Secret.value will return the plain-text string, which you can then pass forward to API calls and other libraries that require it.
from ellf_recipes_sdk import agent_recipe, Secret

@agent_recipe(title="My Recipe")
def recipe(*, api_key: Secret):
    gemini_key = api_key.value()